AI confidence scoring for support teams
AI confidence scoring gives each draft a signal of how sure the model was about it, so agents can spend their review time where it's needed. A routine "where's my order" draft with high confidence gets a quick read. A low-confidence draft on a billing dispute tells the agent to slow down and check the account before sending. In ReplyRabbit, confidence scoring is a Team plan feature: every draft shows how confident the AI is, and the score can also become a FreeScout tag for routing.
What a confidence score tells you
The score reflects how well the draft is supported by what the model had to work with: a clear question, a policy that covers it, a help article that answers it, or order data that confirms it. When those are present, confidence is high. When the question is ambiguous, the policy is silent, or the model had to infer, confidence drops.
It isn't a guarantee either way. A high score can still hide a wrong date; a low score often just means the customer's email was unclear. Treat it as a pointer for attention, not a verdict.
How agents should use it
| Score | What to do |
|---|---|
| High, routine ticket | Read once, check the one or two specifics, send. |
| High, money or reputation involved | Still check every amount and promise. Confidence doesn't verify your records. |
| Low, routine ticket | Read the customer's message again; the draft probably answered the wrong question. |
| Low, sensitive ticket | Treat the draft as notes. Verify with the account, and consider asking a colleague. |
The point is to make review time proportional to risk instead of spreading it evenly.
Why low confidence is useful information
A pattern of low scores on a type of ticket is a gap in what the AI has been given. If refund drafts are consistently low, the refund policy in Company Context is probably incomplete. If product-compatibility drafts are low, a help article is missing or a store connector would help. Each cluster of low scores is a cheap diagnostic for the next improvement to your settings or knowledge sources.
Routing on confidence
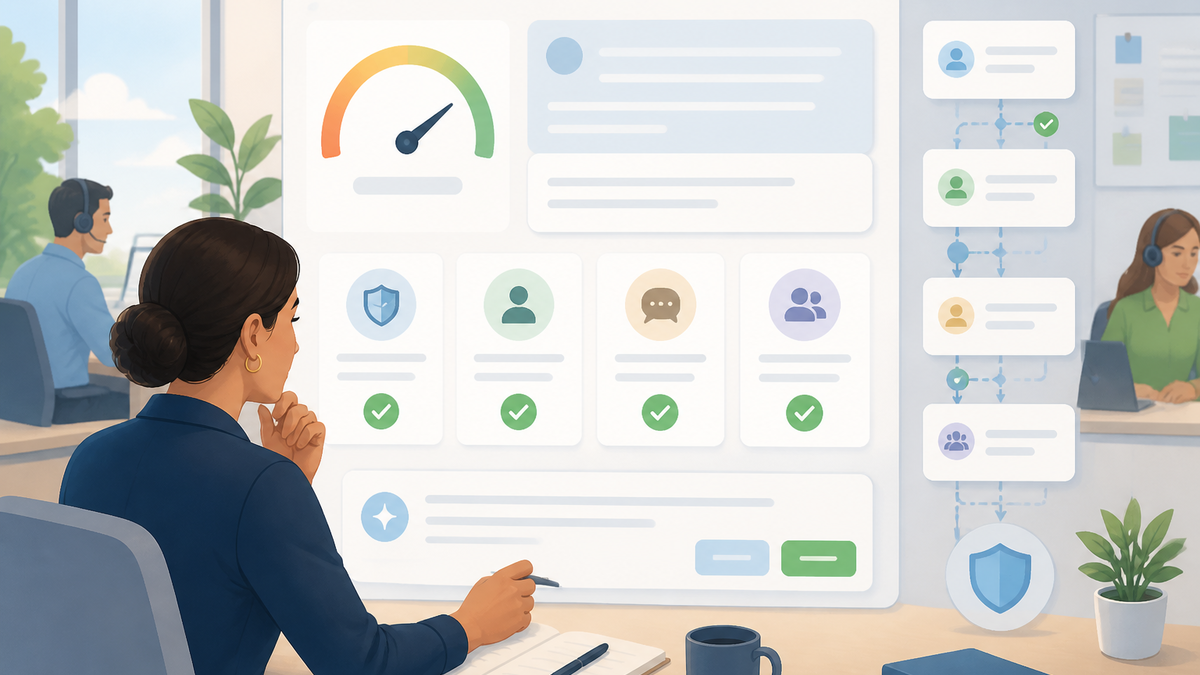
On Pro and Team, AI Signals classify conversations for priority, sentiment, intent, human review and sales opportunity, and Workflow Tags can turn those results into FreeScout tags such as rr_confidence_low and rr_needs_human. If the FreeScout Workflows module is installed and reacts to tag changes, a recipe can assign low-confidence conversations to a senior agent or add a review note. The tag setup is in FreeScout Workflows integration.
What confidence scoring doesn't do
- It doesn't send anything. Every draft, at any score, waits for an agent.
- It doesn't check your records. A confident draft with a wrong refund amount is still wrong.
- It doesn't replace the checklist. Specifics, commitments, tone and recipients still get a look.
Getting it turned on
Confidence scoring is included in the Team plan alongside the audit log and team analytics, which together give a team lead a view of what the AI did, how sure it was, and how much agents changed. Provider and mailbox setup are in How to set up ReplyRabbit, and Choosing an AI provider covers which provider to run it on. If scores or drafts aren't appearing, check Troubleshooting ReplyRabbit and the FAQ.